
NVIDIA HGX vs DGX: The Core Difference
When comparing NVIDIA HGX and DGX platforms, many discussions focus on performance differences and position DGX as the higher-end solution
while considering HGX as a lower-cost alternative. However, this comparison is misleading.
The fundamental difference between HGX and DGX is not GPU capability, but system integration, deployment model, and ownership model.
Both platforms are built around NVIDIA’s high-performance SXM GPU architecture, using the same generation of data center GPUs connected through NVIDIA NVLink and NVSwitch technology. For example, both HGX B200-based systems and DGX B200 systems are built around eight NVIDIA Blackwell B200 GPUs with high-bandwidth GPU interconnects.
However, the final systems differ significantly:
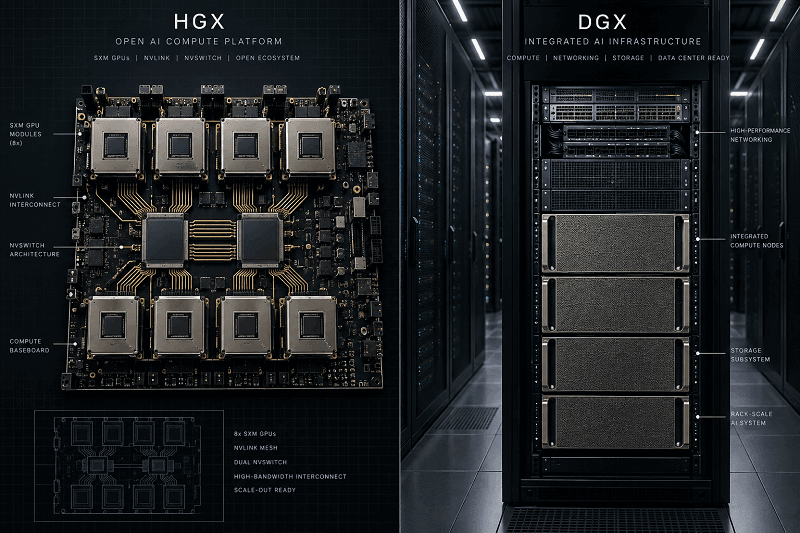
HGX is an AI infrastructure platform. DGX is a complete AI system.
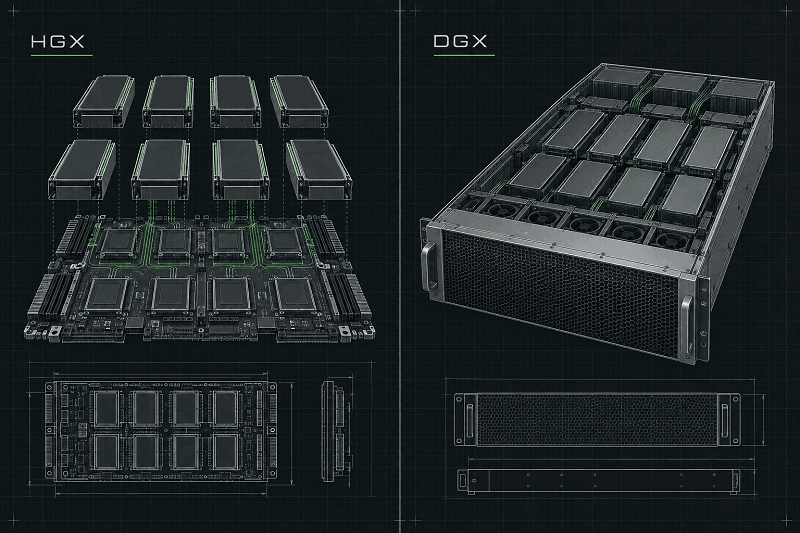
NVIDIA provides HGX as a reference platform for OEM partners, who integrate it into their own server designs with customized CPUs, memory, storage, networking, and thermal solutions.
DGX, on the other hand, is NVIDIA’s fully integrated AI appliance, combining the HGX architecture with validated compute components, networking, software, and enterprise support.
What HGX Actually Includes
An NVIDIA HGX platform is primarily a GPU acceleration platform designed for OEM system integration.
A typical HGX B200 platform includes:
- Eight NVIDIA Blackwell B200 SXM GPUs
- High-speed NVLink GPU interconnect
- NVIDIA NVSwitch technology for GPU-to-GPU communication
- NVIDIA reference designs for power delivery, thermal management, and system integration
HGX does not include the complete server system. The following components are selected and integrated by OEM partners or customers:
- CPU platform
- System memory
- Storage
- Network adapters
- Chassis design
- Operating system and software environment
This flexibility allows cloud providers, hyperscalers, and enterprise customers to build AI clusters optimized for their specific workloads, cost targets, and infrastructure requirements.
HGX serves as the foundation for many large-scale AI systems from NVIDIA’s OEM partners, including solutions from companies such as Dell, Supermicro, Lenovo, HPE, and Gigabyte.
What DGX Adds
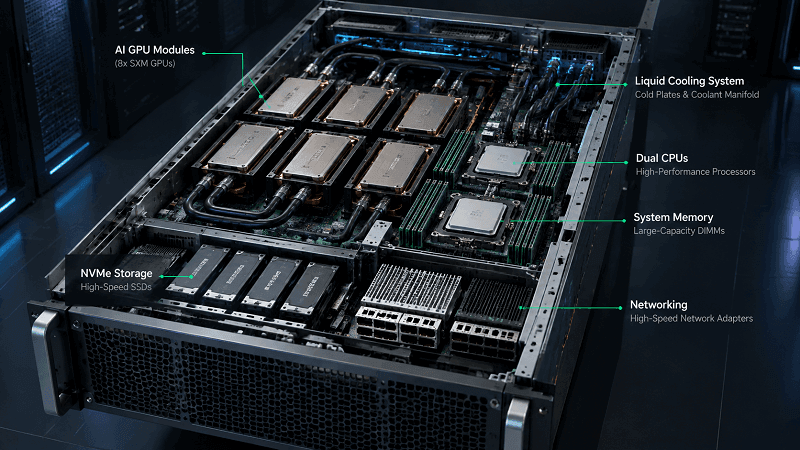
A DGX system takes the same HGX baseboard and wraps a complete server around it. The DGX B200, for example, includes:
- The eight-GPU Blackwell baseboard
- Two Intel Xeon Platinum CPUs
- 2 to 4 TB of system memory
- NVMe storage
- Networking interfaces
- A 10U chassis with integrated cooling
- DGX OS, NVIDIA Base Command, and the NVIDIA AI Enterprise software stack, pre-installed and validated
In practice, the consequence is simple. HGX arrives as a building block that needs integration work. DGX, by contrast, arrives as a machine you can rack and power on. NVIDIA documents the full stack on its DGX platform page.
HGX vs DGX Comparison Table
| Dimension | NVIDIA HGX | NVIDIA DGX |
| What it is | Eight-GPU baseboard plus reference design | Complete, turnkey AI system |
| Built by | OEM partners (Dell, Supermicro, Lenovo, HPE, Gigabyte) | NVIDIA |
| Included | GPUs, NVLink, NVSwitch, power and cooling design | GPUs, CPUs, memory, storage, chassis, networking, OS, software |
| Configuration | Customizable by the OEM or customer | Fixed by NVIDIA |
| Software | NGC stack available, no pre-installed OS | DGX OS, Base Command, NVIDIA AI Enterprise |
| GPU memory (Blackwell) | 1,440 GB HBM3e across eight B200 GPUs | 1,440 GB HBM3e across eight B200 GPUs |
| Peak FP8 (Blackwell) | 72 petaFLOPS on the B200 baseboard | 72 petaFLOPS on the DGX B200 |
| NVLink per GPU | 1.8 TB/s (NVLink 5) | 1.8 TB/s (NVLink 5) |
| Deployment effort | Requires integration and validation | Rack and power on |
| Relative cost | Lower; custom configurations vary widely | Premium, all-inclusive |
| Best for | Cloud providers, large data centers, custom clusters | Enterprises wanting turnkey deployment |
Choose DGX If
DGX is the better choice when:
- You need a production-ready AI system with minimal integration effort
- Your team does not want to manage hardware validation and system optimization
- You prefer a single vendor for hardware, software, and support
- You need a standardized platform for AI training and enterprise deployment
- You want NVIDIA-validated performance and reliability
Choose HGX If
HGX is the better choice when:
- You need a customized AI server architecture
- You already have strong hardware integration capabilities
- You are building large-scale AI clusters with specific infrastructure requirements
- You need flexibility in CPU, memory, storage, or networking selection
- You want to optimize cost across large deployments
For organizations operating at cloud scale, HGX often provides greater flexibility because system design decisions remain under the control of the OEM or infrastructure provider.
NVIDIA HGX vs DGX: Performance in AI Workloads
Because HGX and DGX systems are built around the same NVIDIA GPU architecture, their raw compute capability is generally comparable when configured with the same GPU generation and GPU count.
The main performance difference does not come from the GPUs themselves, but from the surrounding system architecture, software optimization, and deployment environment.
A DGX system may achieve slightly more consistent real-world performance because NVIDIA validates the complete hardware and software stack together, including GPU topology, networking configuration, firmware, and AI software components.
However, an optimized HGX-based system from an experienced OEM can deliver similar AI training and inference performance while providing greater flexibility in system design.
The performance differences become more significant when evaluating complete clusters rather than individual nodes.
Training and Throughput
Large-scale AI model training is limited not only by GPU computing power, but also by memory capacity, GPU communication bandwidth, and cluster networking efficiency.
The NVIDIA Blackwell B200 generation provides:
- Eight B200 SXM GPUs per HGX B200/DGX B200 system
- 180 GB HBM3e memory per GPU
- 1,440 GB total HBM3e memory across eight GPUs
- NVIDIA NVLink 5 interconnect technology
- Up to 1.8 TB/s NVLink bandwidth per GPU
The combination of high-capacity HBM3e memory and high-speed GPU interconnect enables efficient distributed training for large language models, generative AI workloads, and scientific computing applications.
Within a single eight-GPU node, NVSwitch provides high-bandwidth GPU-to-GPU communication, reducing bottlenecks in model parallelism and improving training efficiency.
For the previous Hopper generation, the NVIDIA DGX H100 delivered:
- Eight H100 SXM GPUs
- 900 GB/s NVLink bandwidth per GPU
- 640 GB HBM3 memory capacity
- Up to 32 petaFLOPS FP8 AI performance
The Blackwell B200 generation significantly increases GPU memory capacity and compute performance, enabling larger models and more efficient AI training compared with previous-generation systems.
Inference and Latency
Single-node inference favors DGX. The pre-validated software stack means frameworks are known-good before the machine arrives, so latency tuning starts from a stable baseline. For time-sensitive generative workloads, that head start matters.
HGX is the better fit when inference runs across a fleet. You can tune each node to the model it serves, and you can retire or repurpose individual nodes without replacing an entire NVIDIA-branded system.
Cooling and Power
The rapid growth of AI workloads has significantly increased GPU power density in modern data centers.
The NVIDIA Blackwell generation introduces higher-performance GPUs with significantly higher thermal requirements compared with previous generations.
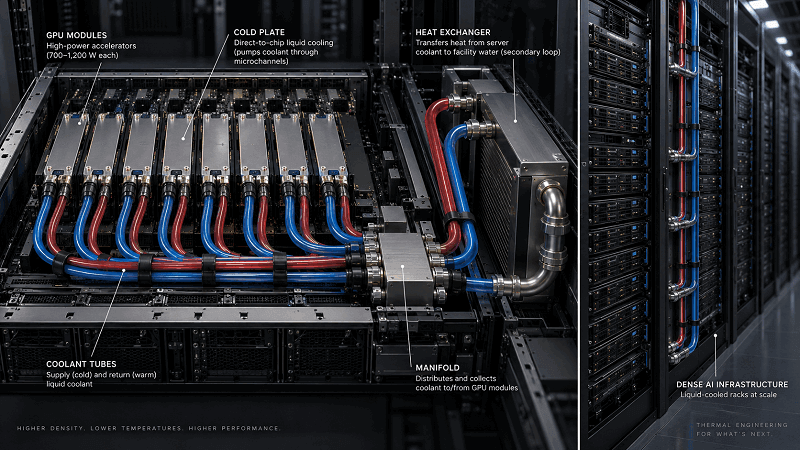
High-end Blackwell SXM GPUs can approach a 1,000-watt power envelope, making traditional air cooling increasingly challenging for dense AI deployments.
As a result, many HGX B200 and GB200-based systems adopt direct liquid cooling solutions, including:
- Cold plates mounted directly on GPUs
- Liquid cooling loops
- Heat exchangers
- Rack-level thermal management systems
The NVIDIA DGX B200 system can consume up to approximately 14.3 kW at maximum configuration and workload conditions.
This level of power density has major implications for:
- Data center rack design
- Power distribution
- Cooling infrastructure
- Network architecture
Organizations deploying large AI clusters must consider power and thermal requirements as early as the infrastructure planning stage.
HGX vs DGX: Cost and Scalability
The biggest difference between HGX and DGX often appears during procurement and large-scale deployment.
While both platforms deliver similar GPU computing capabilities, their business models are different.
HGX focuses on flexibility and customization, while DGX focuses on simplified deployment and integrated support.
Where the Cost Difference Comes From
An HGX system is often cited at roughly 30 percent below an equivalent DGX configuration. The gap comes from three places:
- No NVIDIA integration premium. The OEM assembles and validates the system, not NVIDIA.
- Component choice. You select the CPU, memory, and storage tiers rather than accepting a fixed bundle.
- Support model. Support is split across the OEM and NVIDIA rather than consolidated.
The comparison flips depending on scale. For example, if you need exactly eight GPUs, a DGX is frequently the more cost-effective option once you account for the integration labor, the software licensing, and the support contract. If you need two to four GPUs, however, a full DGX is overpriced for the workload, and an HGX-based server from an OEM is the rational choice.
Scaling to a Cluster
At cluster scale, HGX and DGX follow similar principles.
Both platforms scale by connecting multiple GPU nodes through high-performance networking.
DGX systems can be deployed into NVIDIA reference architectures such as:
- DGX BasePOD
- DGX SuperPOD
HGX-based systems can also be deployed into large-scale AI clusters designed by OEMs, cloud providers, and enterprise infrastructure teams.
At large cluster sizes, the external network becomes a critical factor.
The performance of the AI cluster depends heavily on:
- GPU interconnect architecture
- Scale-out networking
- Network bandwidth
- Latency
- Optical connectivity
As AI clusters continue scaling toward thousands of GPUs, optical networking becomes increasingly important for maintaining efficient distributed training performance.
Which OEMs Ship HGX Systems
Because HGX is a baseboard, you buy it inside somebody else’s server. The main vendors building HGX platforms are:
- Dell (PowerEdge XE series)
- Supermicro (SYS GPU servers)
- Lenovo (ThinkSystem SR series)
- HPE (ProLiant and Apollo)
- Gigabyte (G-series GPU servers)
If you are evaluating HGX, you are really evaluating these vendors, their thermal designs, and their support coverage. NVIDIA does not sell you the baseboard directly.
What This Means for Cluster Cabling
Regardless of whether an organization chooses HGX-based systems or NVIDIA DGX systems, high-performance networking is critical for large-scale AI deployments.
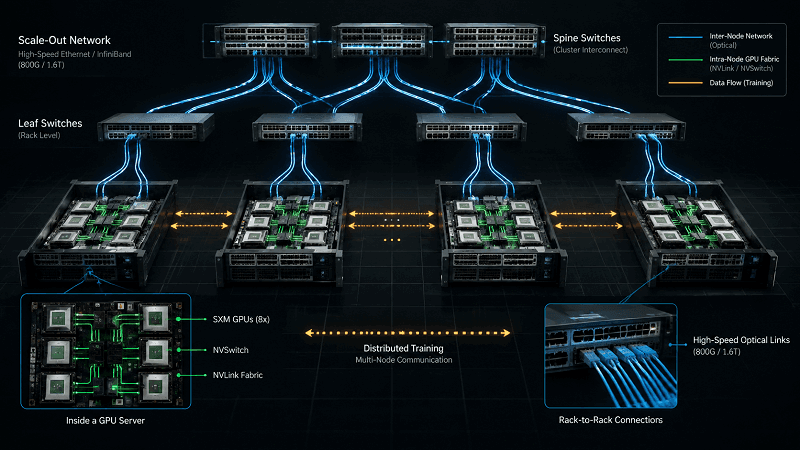
Inside each AI server, GPUs communicate through NVIDIA NVLink and NVSwitch.
However, communication between different servers depends on the external data center network.
For multi-node AI clusters, this scale-out network typically uses high-speed Ethernet or InfiniBand connections, requiring advanced optical transceivers, DAC cables, and fiber infrastructure.
This is where FiberMall provides optical connectivity solutions for AI data centers.
AI Cluster Cabling Considerations
Inside the Rack: High-Speed Copper Connections
For short-distance connections inside racks, copper cables remain a practical choice due to their:
- Low latency
- Low cost
- High reliability
- Simple installation
For 800G AI networking environments, 800G NDR DAC cables are commonly used for short-reach connections between GPU servers and network switches.
Typical applications include:
- AI server-to-switch connections
- Rack-level GPU cluster deployment
- High-density networking environments
Between Racks: Optical Interconnects Become Essential
As distances increase, copper solutions become limited by:
- Signal attenuation
- Cable weight
- Power consumption
- Installation complexity
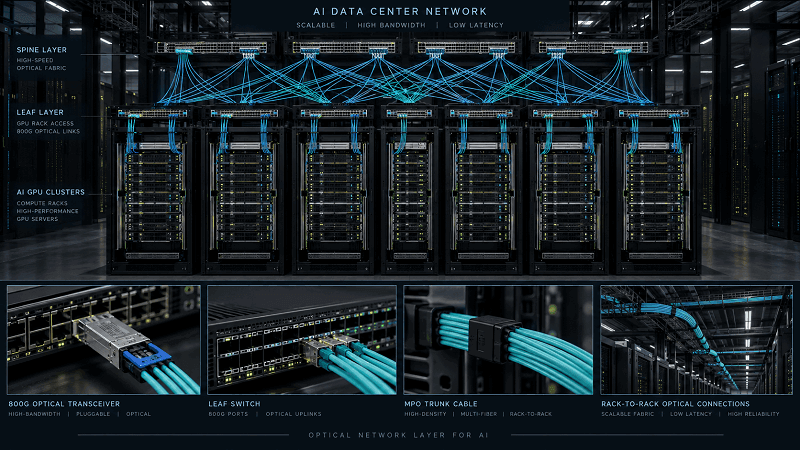
For rack-to-rack connections, optical transceivers provide higher flexibility and longer reach.
800G OSFP optical modules are widely adopted in next-generation AI networks.
Examples include:
800G OSFP DR8
Designed for:
- Single-mode fiber connections
- Data center scale-out networking
- Up to 500-meter transmission distances
These modules are suitable for connecting large AI clusters across multiple racks.
800G OSFP SR8
Designed for:
- Multimode fiber applications
- Shorter data center links
- High-density AI networking environments
Typical reach:
- Approximately 50 meters over OM4 multimode fiber
- Up to around 100 meters depending on fiber conditions and system design
Structured Fiber Cabling for Dense AI Clusters
As AI clusters continue growing, cable management becomes a major challenge.
High-density fiber solutions such as MPO trunk cables help:
- Reduce cable congestion
- Simplify installation
- Improve rack organization
- Support future network upgrades
For large AI training clusters, structured fiber infrastructure is essential for maintaining scalability and operational efficiency.
Preparing for Next-Generation 1.6T Networking
AI workloads continue driving higher bandwidth requirements.
As GPU clusters move beyond 800G networking, 1.6T optical modules are expected to become an important technology for future AI data centers.
1.6T solutions will help support:
- Higher switch port bandwidth
- Larger AI clusters
- More efficient distributed training
- Next-generation GPU architectures
Why Optical Networking Matters for AI Infrastructure
Building an AI cluster is not only about selecting GPUs.
The overall performance depends on the complete infrastructure stack:
- GPU computing capability
- Memory capacity
- GPU interconnect
- Scale-out networking
- Optical connectivity
Once AI deployments expand beyond a single server, network communication becomes a critical factor affecting training efficiency and workload performance.
A well-designed optical network helps ensure that GPU resources can operate efficiently without being limited by external communication bottlenecks.
Frequently Asked Questions
In AI applications, what are the main differences between NVIDIA HGX and NVIDIA DGX?
NVIDIA HGX is an AI infrastructure platform built around NVIDIA’s SXM GPU architecture, NVLink, and NVSwitch technology. It is provided to OEM partners who integrate it into customized AI servers.
NVIDIA DGX is a complete AI system built by NVIDIA, combining HGX architecture with CPUs, memory, storage, networking, validated software, and enterprise support.
The GPUs and GPU interconnect architecture can be equivalent when comparing the same generation and configuration, but DGX provides a more integrated deployment experience.
How does the DGX H100 compare to the HGX H100 in performance?
At the same GPU configuration, HGX H100-based systems and DGX H100 systems use the same eight NVIDIA H100 SXM GPUs and the same NVLink/NVSwitch architecture.
Therefore, their theoretical GPU computing capability is very similar.
The practical difference comes from system integration, including:
- CPU configuration
- Memory design
- Network architecture
- Software optimization
- OEM engineering quality
A well-designed HGX H100 system can achieve comparable performance to DGX H100 while providing more configuration flexibility.
How does the DGX B200 differ from the DGX GB200?
The NVIDIA DGX B200 and DGX GB200 are both based on the Blackwell generation, but they use different system architectures.
The DGX B200 is an x86-based AI system built around:
- Eight NVIDIA B200 SXM GPUs
- Two Intel Xeon Platinum CPUs
- Large-capacity system memory
- High-speed networking
- NVIDIA DGX software stack
The DGX GB200 is based on NVIDIA Grace Blackwell Superchip architecture.
Each GB200 Superchip combines:
- One NVIDIA Grace CPU
- Two NVIDIA Blackwell GPUs
- High-speed NVLink-C2C connectivity between CPU and GPUs
A DGX GB200 system scales this architecture into a rack-scale AI platform designed for extreme-scale AI workloads, including the NVIDIA GB200 NVL72 architecture, which connects 72 Blackwell GPUs within a single rack-scale system.
The two platforms target different AI infrastructure requirements:
- DGX B200 focuses on high-performance single-node and multi-node AI computing.
- DGX GB200 focuses on rack-scale AI systems for the largest generative AI and large language model workloads.
What are the advantages of the NVIDIA HGX H100 platform?
The NVIDIA HGX H100 platform provides the same core Hopper-generation GPU architecture used in DGX H100 systems while offering significantly more flexibility in system design.
Key advantages include:
- Choice of CPU architecture
- Custom memory configurations
- Flexible storage options
- Multiple networking choices
- OEM-specific thermal and mechanical designs
HGX H100 is commonly used by cloud providers, research institutions, and enterprises that need customized AI infrastructure.
Compared with DGX H100, HGX-based systems require more integration work but allow organizations to optimize infrastructure according to workload requirements and operational goals.
How does the NVIDIA HGX vs DGX comparison affect AI infrastructure decisions?
The choice between HGX and DGX depends primarily on an organization’s deployment strategy, technical capabilities, and business requirements.
Choose DGX when:
- Deployment speed is the priority
- Hardware integration resources are limited
- A validated NVIDIA environment is preferred
- Simplified support management is important
Choose HGX when:
- Customization is required
- Large-scale AI clusters are being built
- Hardware integration capabilities already exist
- Infrastructure optimization is a priority
The decision is not about choosing a faster GPU platform. Instead, it is about choosing between a fully integrated AI appliance and a flexible AI infrastructure foundation.
What is the role of NVIDIA data center GPUs in DGX and HGX platforms?
Both NVIDIA HGX and DGX platforms are built around NVIDIA data center GPU architectures.
Different generations include:
- A100 (Ampere architecture)
- H100/H200 (Hopper architecture)
- B200 and GB200 (Blackwell architecture)
The GPU generation determines:
- GPU compute performance
- Memory capacity
- NVLink generation
- Power requirements
- AI workload capabilities
For example:
- HGX H100 and DGX H100 use NVIDIA Hopper GPUs.
- HGX B200 and DGX B200 use NVIDIA Blackwell B200 GPUs.
- DGX GB200 uses NVIDIA Grace Blackwell Superchip architecture.
The GPU architecture is the foundation, while the system design determines how effectively those GPUs are deployed.
Why does the difference between NVIDIA HGX and DGX matter?
The difference matters because it directly affects:
- Deployment speed
- Hardware flexibility
- Infrastructure cost
- Support model
- Long-term scalability
Choosing DGX means investing in a fully integrated NVIDIA AI platform with simplified deployment.
Choosing HGX means gaining more control over system architecture and infrastructure optimization.
Understanding that DGX is built on HGX technology helps organizations make better decisions when designing AI infrastructure.
Conclusion
The comparison between NVIDIA HGX and DGX becomes much clearer once the fundamental difference is understood:
HGX is the foundation. DGX is the finished system.
The two platforms share the same NVIDIA GPU technologies when comparing equivalent configurations, including:
- NVIDIA SXM GPUs
- NVLink high-speed interconnect
- NVSwitch GPU communication fabric
However, their value propositions are different.
The key takeaways:
The silicon architecture is similar
Both HGX and DGX systems use NVIDIA’s advanced data center GPU platforms. The difference is not GPU capability, but how the system is integrated and delivered.
The difference is system design
HGX provides a flexible AI infrastructure platform that OEMs and customers can customize.
DGX provides a complete NVIDIA-validated AI appliance with integrated hardware, software, and support.
Cost depends on deployment scale
DGX can provide better value for organizations that need rapid deployment and simplified operations.
HGX can provide better economics for organizations building large-scale customized AI infrastructure.
Blackwell defines the next AI infrastructure generation
The NVIDIA Blackwell platform introduces:
- Up to 1,440 GB HBM3e memory across eight B200 GPUs
- Up to 1.8 TB/s NVLink bandwidth per GPU
- Significant improvements in AI training and inference performance
These capabilities enable larger AI models and more efficient distributed computing.
Networking becomes the critical factor at scale
Once AI workloads expand beyond a single server, external networking becomes a major performance factor.
High-performance AI clusters require:
- High-speed Ethernet or InfiniBand networks
- 800G optical transceivers
- High-density fiber cabling
- Advanced DAC solutions
- Future-ready 1.6T connectivity
The optical layer determines how efficiently thousands of GPUs can communicate during distributed training and inference.
Whether you choose NVIDIA HGX-based infrastructure or NVIDIA DGX systems, FiberMall provides the optical connectivity solutions required for next-generation AI data centers.
Our engineers help customers design complete network solutions, including:
- 800G OSFP optical transceivers
- 800G NDR DAC cables
- MPO fiber trunk systems
- High-density data center cabling solutions
- Next-generation 1.6T optical technologies
From GPU clusters to AI networking infrastructure, FiberMall helps organizations build scalable, reliable, and high-performance AI data center networks.
Related Products:
-
 NVIDIA MMA4Z00-NS400 Compatible 400G OSFP SR4 Flat Top PAM4 850nm 30m on OM3/50m on OM4 MTP/MPO-12 Multimode FEC Optical Transceiver Module
$400.00
-
NVIDIA MMA4Z00-NS-FLT Compatible 800GBASE 2 x SR4/SR8 OSFP RHS/Flat Top PAM4 850nm 100m DOM Dual MPO-12 MMF Optical Transceiver Module
$600.00
-
NVIDIA MMA4Z00-NS Compatible 800GBASE 2 x SR4/SR8 OSFP PAM4 850nm 100m DOM Dual MPO-12 MMF Optical Transceiver Module
$550.00
-
NVIDIA MMS4X00-NM Compatible 800GBASE 2 x DR4/DR8 OSFP IHS/Closed Finned Top PAM4 1310nm 500m DOM Dual MTP/MPO-12 SMF Optical Transceiver Module
$600.00
-
NVIDIA MMS4X00-NM-FLT Compatible 800GBASE 2 x DR4/DR8 OSFP Flat Top PAM4 1310nm 500m DOM Dual MTP/MPO-12 SMF Optical Transceiver Module
$650.00
-
NVIDIA MMS4X00-NS400 Compatible 400G OSFP DR4 Flat Top PAM4 1310nm MTP/MPO-12 500m SMF FEC Optical Transceiver Module
$450.00
-
NVIDIA(Mellanox) MMA1T00-HS Compatible 200G Infiniband HDR QSFP56 SR4 850nm 100m MPO-12 APC OM3/OM4 FEC PAM4 Optical Transceiver Module
$139.00
-
NVIDIA MFP7E10-N010 Compatible 10m (33ft) 8 Fibers Low Insertion Loss Female to Female MPO Trunk Cable Polarity B APC to APC LSZH Multimode OM3 50/125
$47.00
-
NVIDIA MCP7Y00-N003-FLT Compatible 3m (10ft) 800G Twin-port OSFP to 2x400G Flat Top OSFP InfiniBand NDR Breakout DAC
$260.00
-
NVIDIA MCP7Y70-H002 Compatible 2m (7ft) 400G Twin-port 2x200G OSFP to 4x100G QSFP56 Passive Breakout Direct Attach Copper Cable
$155.00
-
NVIDIA MCA4J80-N003-FTF Compatible 3m (10ft) 800G Twin-port 2x400G OSFP to 2x400G OSFP InfiniBand NDR Active Copper Cable, Flat top on one end and Finned top on other
$600.00
-
NVIDIA MCP7Y10-N002 Compatible 2m (7ft) 800G InfiniBand NDR Twin-port OSFP to 2x400G QSFP112 Breakout DAC
$190.00